AndrewLBorges/RealTime_Analytics_With_Python_Spark.Learning to work with Apache Spark and Python by creating Study Cases and some small projects. About.
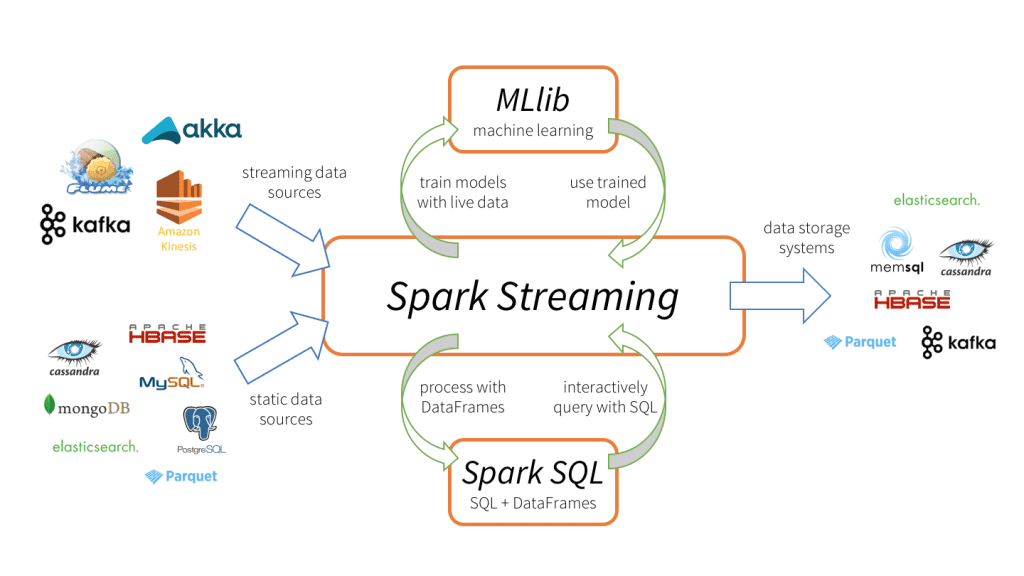
Apache Spark is a multi-language engine for executing data engineering, data science, and machine learning on single-node machines or clusters. Simple.Unify the processing of your data in batches and real-time streaming, using your preferred language: Python, SQL, Scala, Java or R.
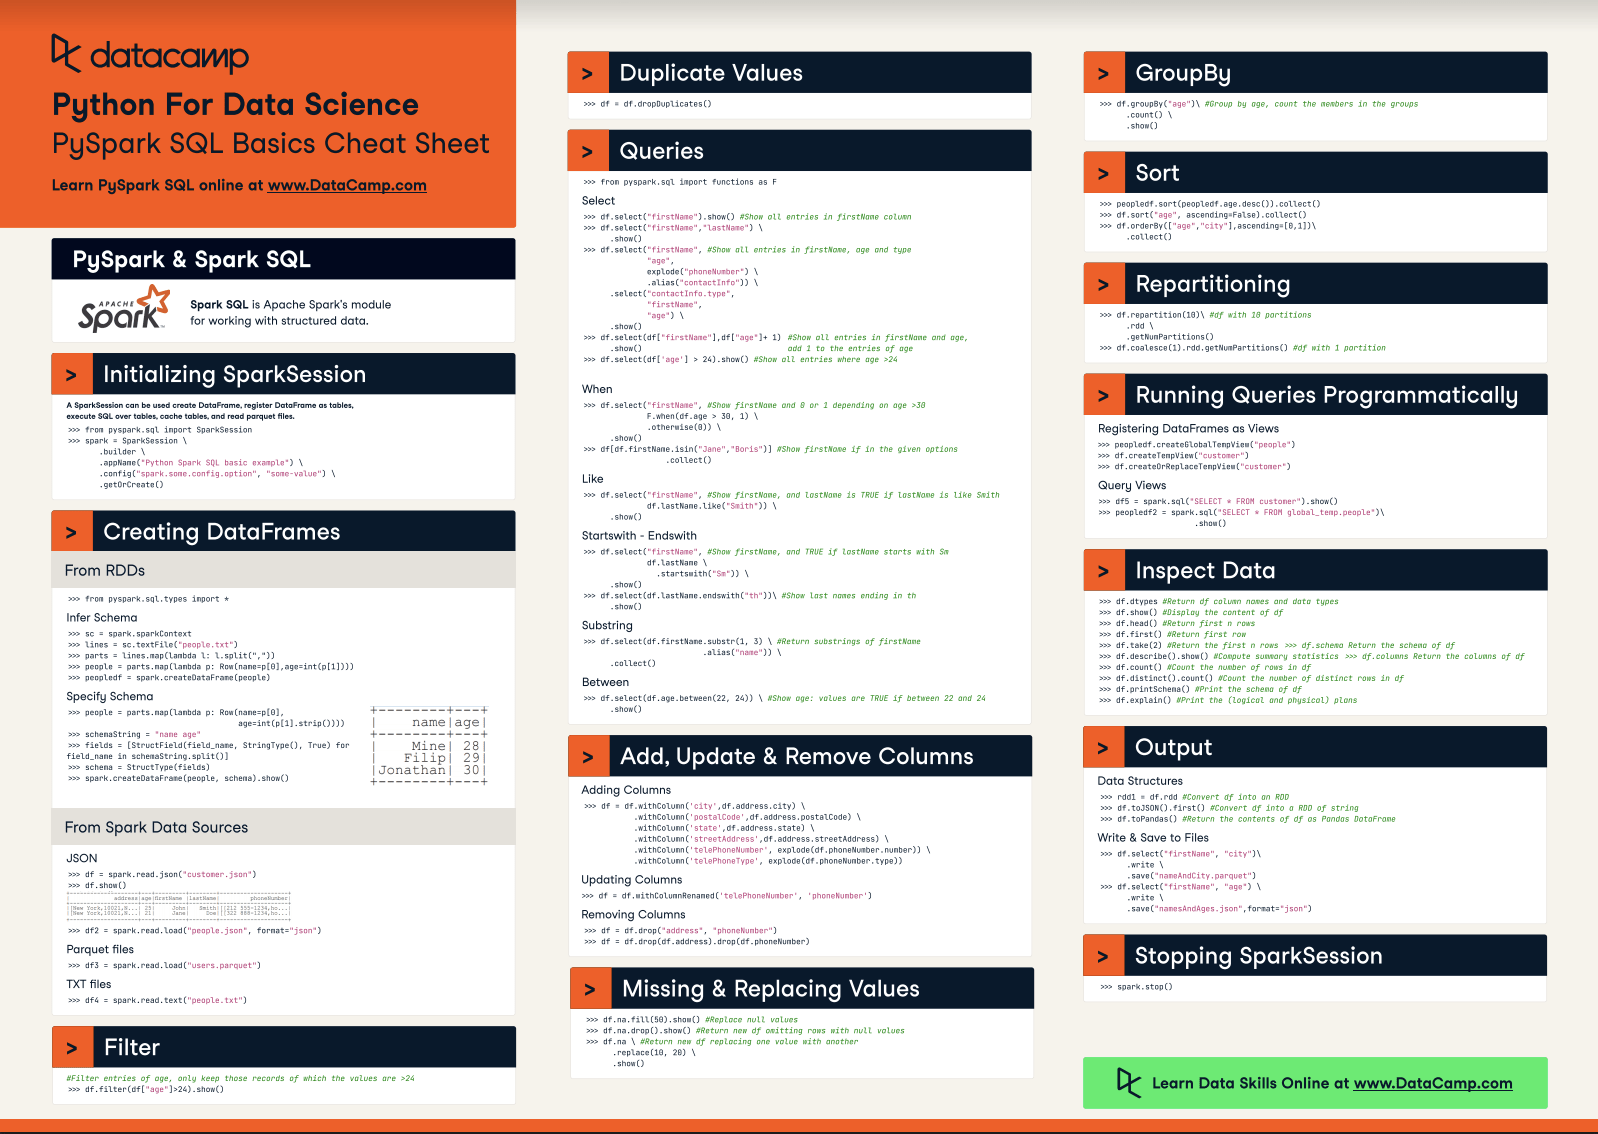
Learn PySpark, an interface for Apache Spark in Python. PySpark is often used for large-scale data processing and machine learning. Code: https://github.co...
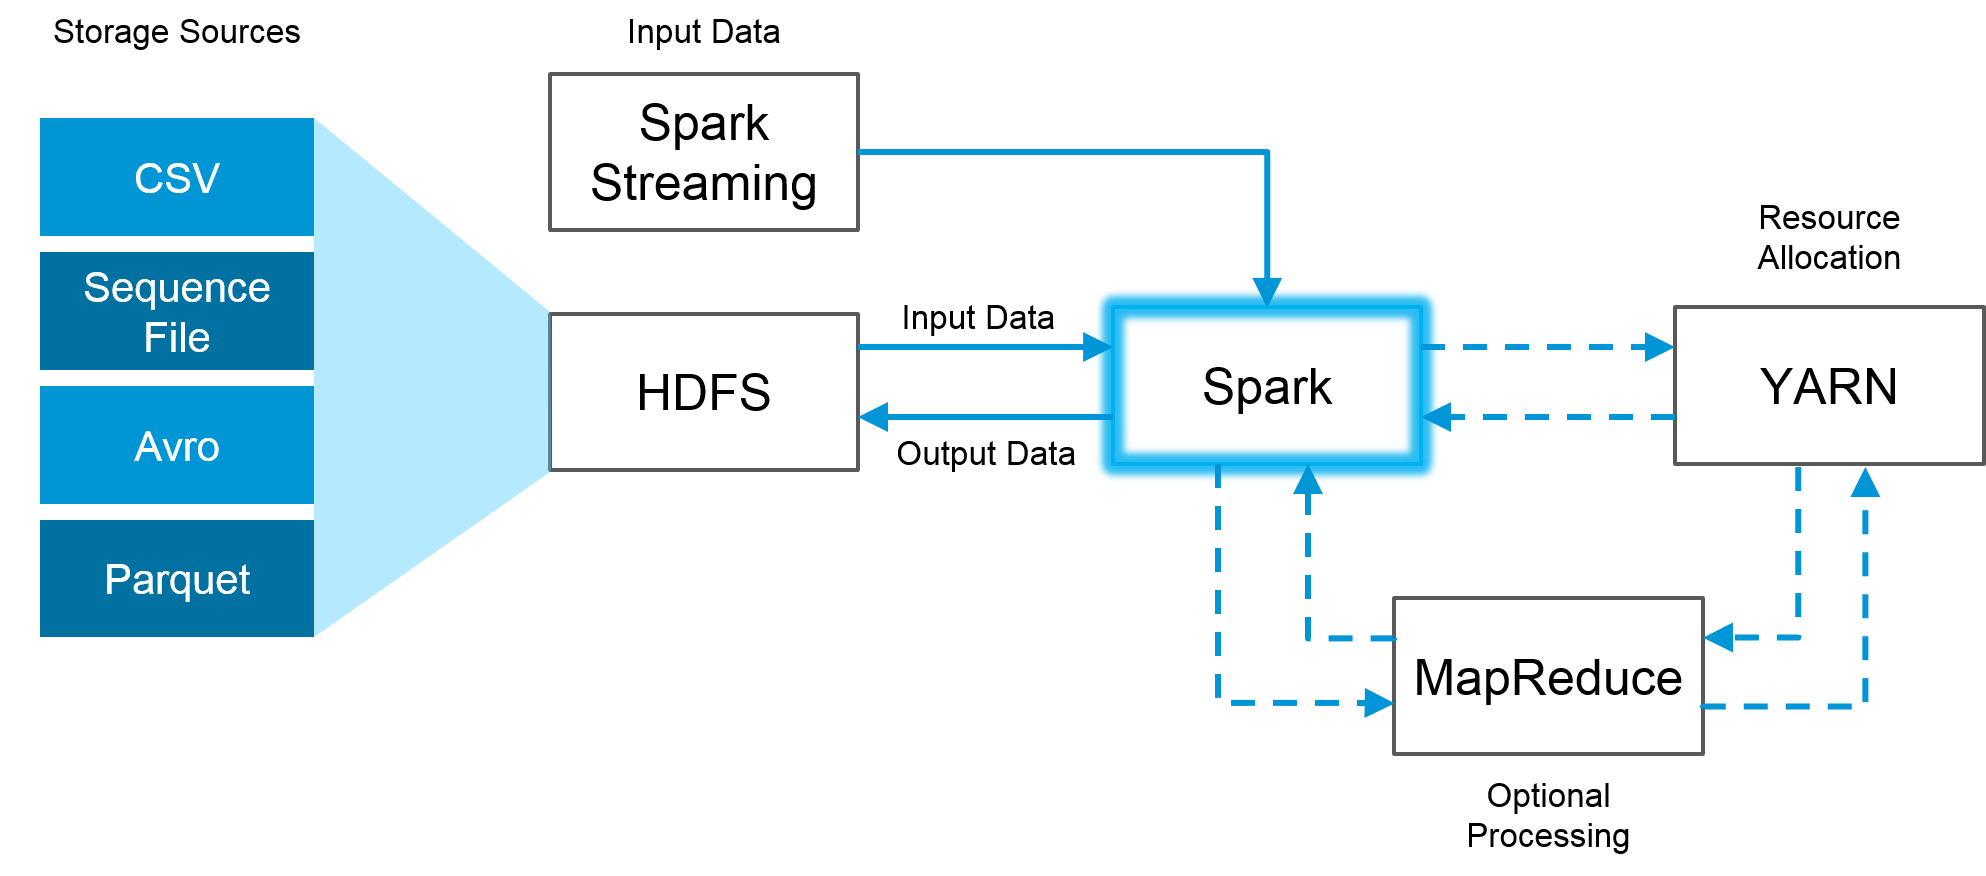
Spark is a unified analytics engine for large-scale data processing.You can find the latest Spark documentation, including a programming guide, on the project web page. Python Packaging. This README file only contains basic information related to pip installed PySpark.

Apache Spark is a multi-language engine for executing data engineering, data science, and machine learning on single-node machines or clusters. It provides high-level APIs in Scala, Java, Python, and R, and an optimized engine that supports general computation graphs for data analysis.
How can I use Spark with Python? Apache Spark allows you to speed up...
#Python + #Spark = PySpark ( the Python API for Apache Spark, an open source, distributed computing #framework and set of libraries for #realtime, #largescale #dataprocessing).

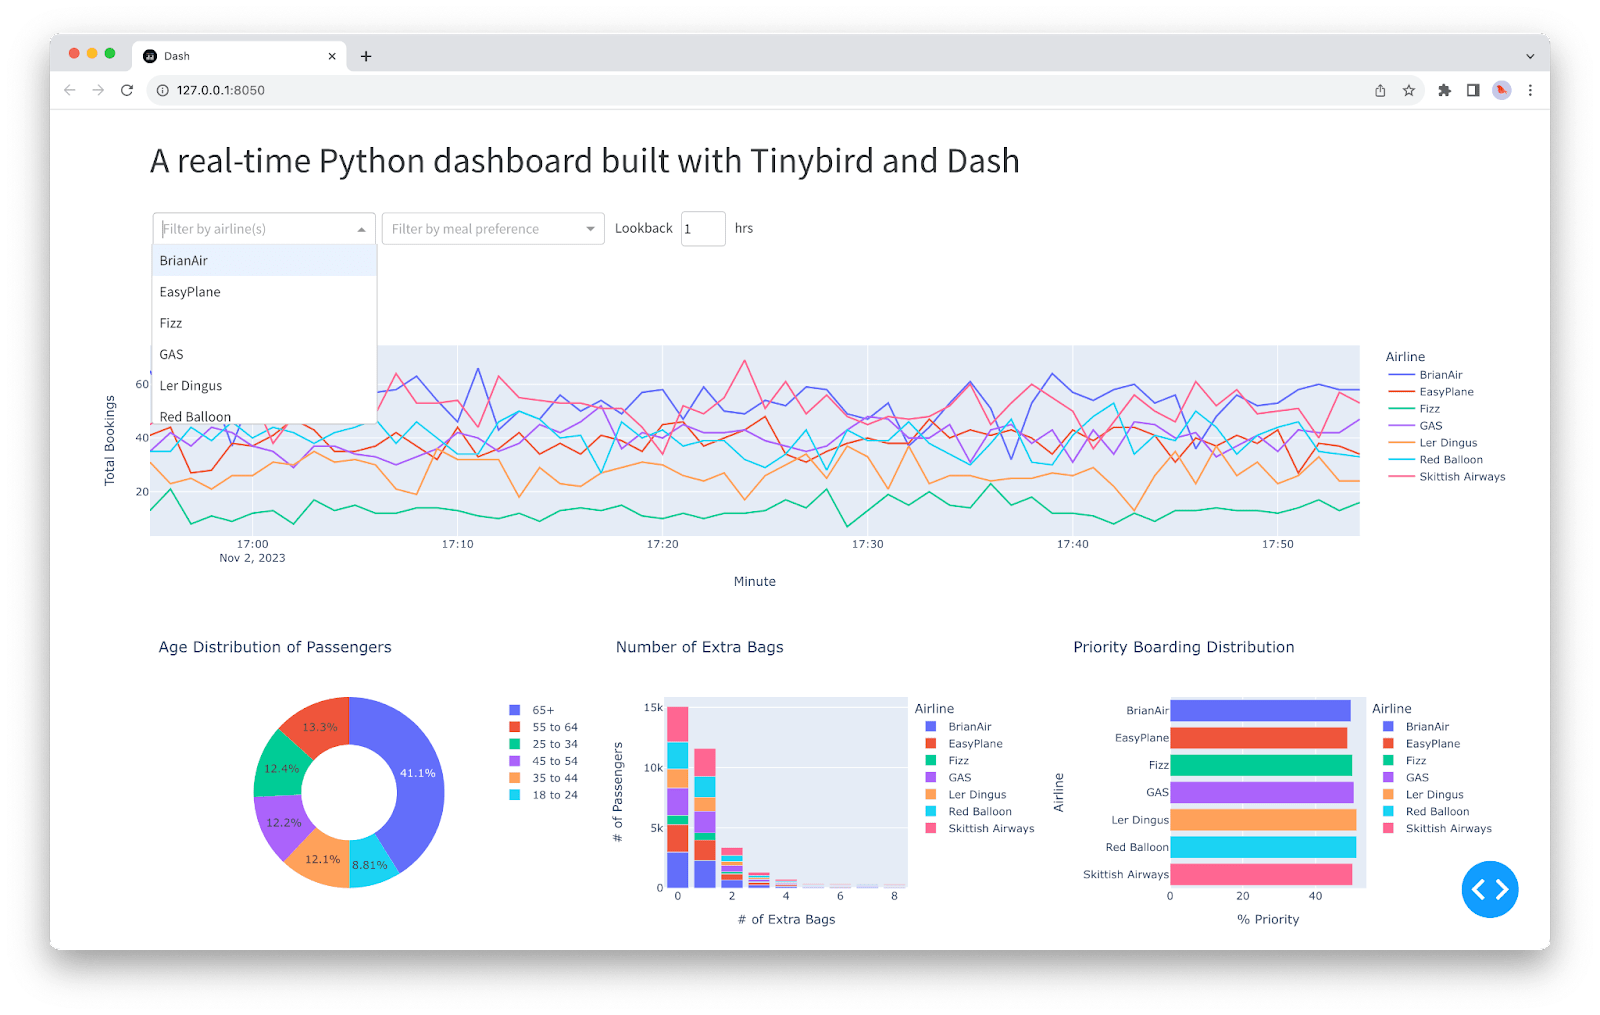
Real-Time Data Analytics Important note Spark's Structured Streaming, with its micro-batch style of stream processing model, isn't well suited for real-time stream processing use cases where there is an ultra-low latency requirement to process events as they happen at the source.
Spark is a distributed parallel computation framework but still there are some functions which can be parallelized with python multi-processing Module. Let us see the following steps in detail. Sequential execution of Pyspark function. Horizontal Parallelism with ThreadPool. How does it work.